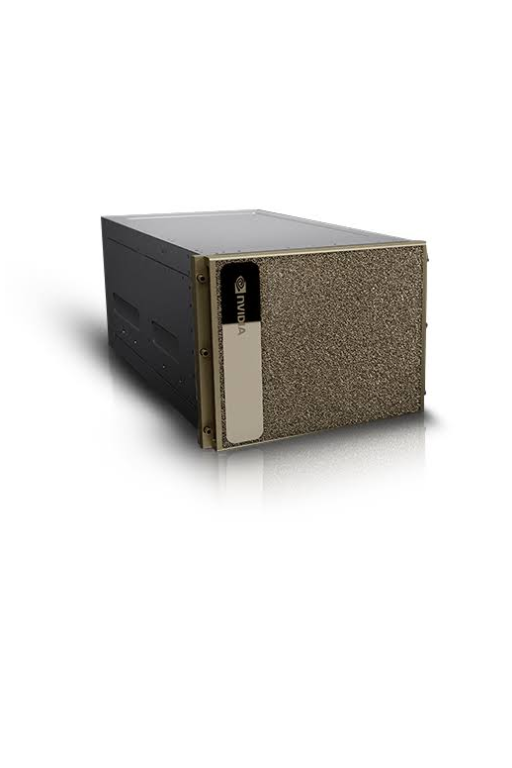

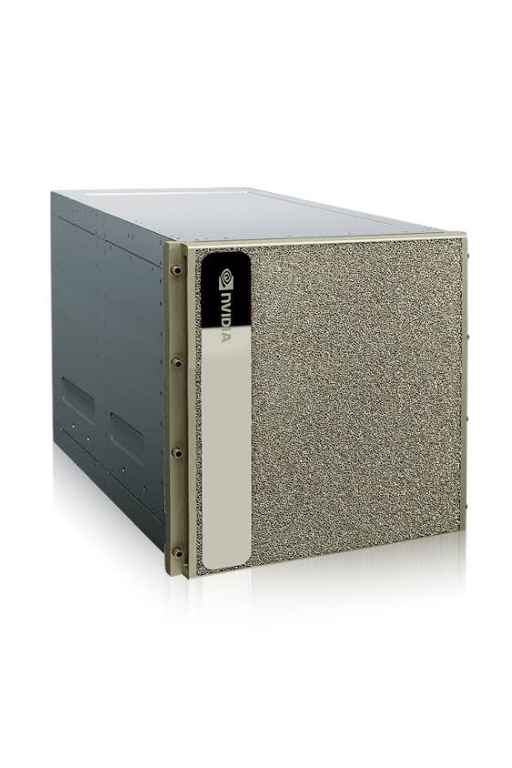
NVIDIA DGX B200 AI Supercomputer
The NVIDIA DGX B200 is an enterprise-class AI supercomputer designed for large-scale generative AI, large language models (LLMs), deep learning, high-performance computing (HPC), data analytics, and accelerated computing.
Powered by 8 NVIDIA Blackwell B200 Tensor Core GPUs, DGX B200 delivers 1.44TB of total HBM3e GPU memory, up to 64TB/s aggregate GPU memory bandwidth, and up to 72 PFLOPS of FP8 AI performance with sparsity. The system combines Blackwell GPUs with fourth-generation NVLink, fifth-generation NVLink Switch technology, dual Intel Xeon CPUs, 2TB system memory, 30TB of NVMe storage, and high-speed ConnectX-7 networking.
DGX B200 is engineered as a complete, validated AI infrastructure platform for organizations deploying demanding AI training and inference workloads at enterprise and data-center scale.
Description
The NVIDIA DGX B200 represents a major generation of NVIDIA’s integrated DGX AI infrastructure, combining the Blackwell architecture with high-bandwidth GPU interconnects, enterprise networking, large system memory, high-speed storage, and a comprehensive NVIDIA software stack.
It is designed to operate as an integrated AI platform rather than simply an 8-GPU server, providing the infrastructure required for large-scale model training, inference, fine-tuning, and data-intensive accelerated computing.
Eight NVIDIA Blackwell B200 GPUs
DGX B200 incorporates 8 NVIDIA B200 Tensor Core GPUs.
The eight GPUs provide:
- 1.44TB total HBM3e memory
- 180GB HBM3e per GPU
- Up to 64TB/s aggregate GPU memory bandwidth
- Fifth-generation Tensor Cores
- Second-generation Transformer Engine
- Fourth-generation NVLink
- Advanced FP4, FP6, FP8, BF16, FP16 and TF32 acceleration
The B200 GPUs are designed specifically for modern AI workloads, particularly transformer-based models and generative AI.
Blackwell Architecture
NVIDIA Blackwell introduces major advances in AI computing, including:
- Fifth-generation Tensor Cores
- Second-generation Transformer Engine
- FP4 precision support
- FP6 precision support
- Advanced sparsity
- Decompression Engine
- Confidential Computing capabilities
- High-speed GPU interconnects
These technologies allow DGX B200 to accelerate both training and inference while improving the efficiency of large-scale AI workloads.
1.44TB of HBM3e GPU Memory
Each B200 GPU provides 180GB of HBM3e memory.
Across eight GPUs, DGX B200 provides:
8 × 180GB = 1.44TB HBM3e
The memory subsystem delivers approximately 64TB/s aggregate GPU memory bandwidth, enabling extremely high-throughput movement of model parameters, activations, datasets, and intermediate results.
This large shared GPU-memory capacity is particularly important for large language models and other AI workloads with very large parameter sets.
NVIDIA NVLink and NVLink Switch
DGX B200 uses NVIDIA’s high-speed GPU interconnect architecture to allow the eight GPUs to communicate efficiently.
The system incorporates:
- Fourth-generation NVLink
- Fifth-generation NVLink Switch technology
- High-bandwidth GPU-to-GPU communication
- Low-latency communication between GPUs
This enables DGX B200 to function as a tightly integrated multi-GPU computing platform for distributed AI workloads.
AI Performance
DGX B200 provides up to approximately:
- 72 PFLOPS FP8 AI performance with sparsity
- 36 PFLOPS FP16/BF16 AI performance with sparsity
- 18 PFLOPS TF32 performance with sparsity
The exact performance depends on precision, workload, sparsity, and whether the benchmark represents theoretical peak or application performance.
NVIDIA positions DGX B200 specifically for training and inference of large AI models, including generative AI and trillion-parameter-class workloads.
Dual Intel Xeon CPUs
DGX B200 incorporates two Intel Xeon Platinum 8570 processors.
Together, the CPUs provide:
- 112 CPU cores
- 56 cores per processor
- High-throughput host processing
- Large PCIe connectivity
- Support for large system-memory configurations
The CPU subsystem handles host-side application processing, data preparation, orchestration, storage, networking, and system management.
2TB System Memory
The DGX B200 includes 2TB of DDR5 system memory.
This provides substantial host-memory capacity for:
- Large datasets
- Data preprocessing
- AI pipelines
- Model staging
- HPC workloads
- Large-scale analytics
- Multi-GPU applications
30TB NVMe Storage
DGX B200 includes approximately 30TB of internal NVMe storage.
The standard configuration uses:
- 2 × 1.92TB NVMe M.2 drives for the operating system
- 8 × 3.84TB NVMe U.2 drives for data/cache storage
The high-speed NVMe subsystem provides local storage for AI models, datasets, checkpoints, containers, temporary data, and operating-system resources.
High-Speed ConnectX-7 Networking
DGX B200 integrates NVIDIA ConnectX-7 network adapters for high-speed external connectivity.
The system provides:
- 8 × ConnectX-7 single-port 400Gb/s adapters
- 2 × ConnectX-7 dual-port 200Gb/s adapters
- Up to 1.6Tb/s aggregate network bandwidth
- InfiniBand and Ethernet support
This high-speed networking architecture is designed for multi-node DGX clusters, AI factories, DGX SuperPOD environments, distributed training, and high-performance storage.
BlueField-3 DPU
DGX B200 incorporates NVIDIA BlueField-3 DPUs for infrastructure acceleration and isolation.
These DPUs can offload infrastructure services such as:
- Networking
- Storage
- Security
- Virtualization
- Infrastructure management
This allows host CPUs and GPUs to remain focused on application and AI workloads.
Enterprise AI Software
DGX B200 is designed around NVIDIA’s integrated software ecosystem.
Supported software technologies include:
- NVIDIA DGX OS
- CUDA
- NVIDIA AI Enterprise
- NVIDIA Base Command
- NVIDIA Magnum IO
- NVIDIA NIM
- TensorRT
- TensorRT-LLM
- PyTorch
- NVIDIA GPU drivers
- NVIDIA networking software
This provides a validated environment for developing, training, deploying, and managing enterprise AI workloads.
3. Complete Technical Specification
| Specification | Details |
|---|---|
| Product Name | NVIDIA DGX B200 |
| Product Type | Enterprise AI Supercomputer / AI Server |
| GPU Architecture | NVIDIA Blackwell |
| GPU | 8 × NVIDIA B200 Tensor Core GPU |
| GPU Form Factor | SXM |
| GPU Memory per GPU | 180GB HBM3e |
| Total GPU Memory | 1.44TB HBM3e |
| Aggregate GPU Memory Bandwidth | Up to 64TB/s |
| Tensor Cores | 5th Generation |
| Transformer Engine | 2nd Generation |
| RT Cores | 4th Generation |
| FP8 Performance | Up to 72 PFLOPS with sparsity |
| FP16/BF16 Performance | Up to 36 PFLOPS with sparsity |
| TF32 Performance | Up to 18 PFLOPS with sparsity |
| GPU Interconnect | 4th-generation NVLink |
| NVLink Switch | 5th-generation NVLink Switch |
| CPU | 2 × Intel Xeon Platinum 8570 |
| CPU Cores | 112 total |
| System Memory | 2TB DDR5 |
| High-Speed Networking | ConnectX-7 |
| InfiniBand Networking | Up to 400Gb/s |
| Ethernet Networking | Up to 400GbE |
| Aggregate Network Bandwidth | Up to 1.6Tb/s |
| High-Speed Network Adapters | 8 × single-port 400Gb/s ConnectX-7 |
| Additional Network Adapters | 2 × dual-port 200Gb/s ConnectX-7 |
| DPU | NVIDIA BlueField-3 |
| Internal Storage | Approximately 30TB NVMe |
| OS Storage | 2 × 1.92TB NVMe M.2 |
| Data Storage | 8 × 3.84TB NVMe U.2 |
| Operating System | NVIDIA DGX OS |
| AI Software | CUDA, NVIDIA AI Enterprise, Base Command, Magnum IO |
| Form Factor | 10U data-center system |
| Primary Workloads | AI training, inference, generative AI, HPC |
| Deployment | Enterprise data center / AI factory |
4. Applications
Artificial Intelligence & Machine Learning
- Large language model training
- Generative AI
- Transformer models
- Multimodal AI
- Computer vision
- Speech and language models
- Recommendation systems
- AI inference
- Model fine-tuning
High-Performance Computing
- Scientific simulations
- Engineering simulation
- Computational chemistry
- Molecular dynamics
- Climate modeling
- Genomics
- Financial modeling
- Large-scale numerical computing
Enterprise Generative AI
- Enterprise LLM platforms
- Retrieval-augmented generation (RAG)
- AI agents
- Natural-language processing
- Enterprise knowledge assistants
- Generative image and video workloads
- AI-powered analytics
AI Infrastructure
- DGX SuperPOD
- NVIDIA AI factories
- Private AI clouds
- Large GPU clusters
- Multi-node distributed training
- Enterprise AI infrastructure
- Research supercomputing
5. Compatibility
DGX B200 is a complete NVIDIA-integrated data-center system and is not intended to be treated like a conventional workstation where individual GPUs are freely substituted.
It is designed for integration with:
- NVIDIA DGX SuperPOD infrastructure
- NVIDIA AI factories
- NVIDIA Quantum InfiniBand networking
- NVIDIA Spectrum Ethernet networking
- ConnectX-7 adapters
- BlueField-3 DPUs
- High-performance NVMe storage
- NVIDIA AI Enterprise
- NVIDIA Base Command
- CUDA-based AI applications
- PyTorch and TensorRT workloads
- Multi-node GPU clusters
For cluster deployments, the system can use high-speed InfiniBand or Ethernet networking to communicate with additional DGX B200 systems and compatible NVIDIA networking infrastructure.
Compatibility Note: DGX B200 uses an integrated NVIDIA architecture with SXM GPUs, NVLink/NVSwitch fabric, specialized cooling, networking, storage, and power infrastructure. Individual components should only be replaced with NVIDIA-approved or system-qualified equivalents.
6. Key Benefits
- 8 × NVIDIA B200 Blackwell GPUs
- 1.44TB total HBM3e GPU memory
- Up to 64TB/s aggregate GPU memory bandwidth
- Up to 72 PFLOPS FP8 AI performance with sparsity
- Fifth-generation Tensor Cores
- Second-generation Transformer Engine
- Fourth-generation NVLink
- Fifth-generation NVLink Switch
- 112 Intel Xeon CPU cores
- 2TB DDR5 system memory
- Approximately 30TB NVMe storage
- Up to 1.6Tb/s aggregate networking
- 400Gb/s ConnectX-7 networking
- Integrated BlueField-3 DPUs
- Designed for large-scale generative AI
- Optimized for distributed AI training and inference
- Enterprise-grade NVIDIA software stack
- Designed for DGX SuperPOD and AI factory deployments
- High-speed GPU, storage, and networking architecture
- Suitable for demanding AI and HPC workloads
7. SEO Title
NVIDIA DGX B200 AI Supercomputer – 8× B200, 1.44TB HBM3e, 2TB RAM, 400Gb/s
Related products
-
Oracle/Sun 7093015 600GB 10K RPM SAS-3 2.5″ Hard Drive Assembly with Caddy
Read more
Oracle/Sun 7093015 600GB 10K RPM SAS-3 2.5″ Hard Drive Assembly with Caddy
The Oracle/Sun 7093015 is a 600GB 10,000 RPM SAS-3 enterprise hard drive assembly designed for compatible Oracle Exadata server and storage platforms. Featuring a 2.5-inch form factor and high-speed 12Gb/s SAS-3 interface, this drive assembly provides reliable, high-performance storage for enterprise workloads, system replacement, maintenance, and data-center infrastructure.
Quick View -
Cisco AIR-AP1852I-I-K9 Aironet 1850 Series Access Point
Read more Cisco AIR-AP1852I-I-K9 Aironet 1850 Series Wireless Access Point
The Cisco Aironet AIR-AP1852I-I-K9 is a high-performance dual-band enterprise wireless access point featuring 802.11ac Wave 2, 4×4 MIMO, four spatial streams, and integrated omnidirectional antennas. Designed for indoor enterprise environments, it delivers up to 1.7 Gbps on the 5 GHz radio and supports advanced technologies such as MU-MIMO, transmit beamforming, Cisco FlexConnect, and Mobility Express for scalable, reliable wireless connectivity.
Quick View -

Arista Compatible 40G QSFP+ to 10G SFP+ Adapter Converter Module
Read more
Arista Compatible 40G QSFP+ to 10G SFP+ Adapter Converter Module
The Arista QSFP-SFP10G adapter is a converter module designed to provide 10 Gigabit Ethernet and 1 Gigabit Ethernet connectivity through 40G QSFP+ ports. It enables compatible Arista QSFP-only platforms to use lower-speed SFP/SFP+ modules, providing a practical and cost-effective solution for network migration, connectivity expansion, and mixed-speed Ethernet environments.
Quick View -
Juniper SRX300-SYS-JB
Read more
Juniper SRX300-SYS-JB SRX300 Services Gateway is a compact branch firewall and services gateway that combines 8 Gigabit Ethernet ports, 4GB RAM, 8GB Flash, and Junos Software Base in a single platform. It provides integrated firewall, NAT, IPsec VPN, routing, MPLS, and switching capabilities for small and medium-sized branch and enterprise networks.
Quick View
